缓存命中率 99.3% 意味着什么?5547 万 token 真实账单拆解

大模型 API 定价页面看着都一样,但同一个模型在不同厂商、不同套餐下的实际账单能差十几倍。差异到底在哪?拿我一次真实的 Agent 编码任务账单算一遍就明白了。

先看用量:这个账单长什么样

指标数值占比
总 token55,474,539100%
输入(缓存命中)55,084,92899.30%
输入(未命中)212,1190.38%
输出177,4920.32%

这个分布很典型:99.3% 是缓存命中。原因是 Agent 编码场景里,系统提示词和项目文件每一轮都要重新读进去,但因为前缀完全相同,被缓存命中了。缓存命中价和未命中价差 50 倍,这一项直接决定账单。

第一站:DeepSeek 官方按量(基准)

时段输入未命中输入缓存命中输出
空闲¥1¥0.02¥4
高峰¥2¥0.04¥8
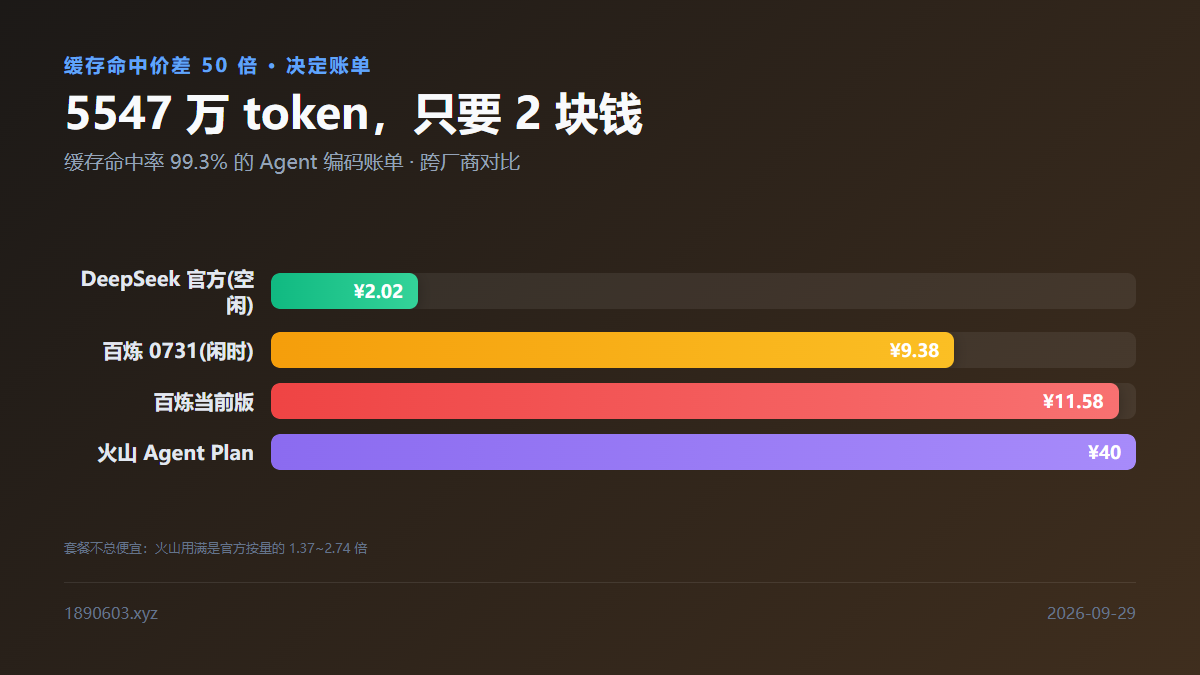
同一份 5547 万 token 用量在四个服务商线路下的实际成本对比

单位都是元/百万 token。代入本次用量(空闲时段):

空闲:55,084,928×0.02/1e6 + 212,119×1/1e6 + 177,492×4/1e6 = ¥2.02
高峰:55,084,928×0.04/1e6 + 212,119×2/1e6 + 177,492×8/1e6 = ¥4.05

官方价区间 = ¥2.02 ~ ¥4.05
先记住这个数5547 万 token,官方按量只要 2~4 块钱。这是后面所有对比的基准。

第二站:火山方舟 Agent Plan(套餐反而不划算)

火山方舟的计费单位叫 AFP,公式是 AFP = (输入token×0.5 + 输出token×0.5) / 10000。关键点:AFP 不区分缓存命中,全按同一个系数算。

AFP = 55,474,539 × 0.5 / 10000 = 2,773.73 AFP

各档位对比

档位月费AFP 额度本次占额度
Small¥4020,00013.87%
Medium¥200100,0002.77%
Large¥500250,0001.11%
Max¥1,000500,0000.55%

如果用满套餐呢?20,000 AFP = 4 亿 token,按本次的 99.3% 命中率折算成官方价:

档位套餐价满额官方等价倍数
Small¥40¥14.59 ~ ¥29.192.74 ~ 1.37×
Medium¥200¥72.9 ~ ¥145.92.74 ~ 1.37×
Large¥500¥182.4 ~ ¥364.82.74 ~ 1.37×
Max¥1,000¥364.8 ~ ¥729.62.74 ~ 1.37×
结论有点反直觉:用满套餐时,套餐价是官方按量的 1.37~2.74 倍。原因是官方缓存命中价只有 ¥0.02/M,低到离谱;而套餐的 AFP 不区分缓存,全按一个系数算。套餐的价值不在便宜,在于多模型切换 + 预算固定不超支。

第三站:阿里百炼(明显更贵)

版本输入/输出/缓存本次用量价格
当前版 deepseek-v4-flash1 / 2 / 0.2¥11.58
0731 快照(闲时)1.5 / 4.5 / 0.15¥9.38
0731 快照(忙时)3 / 9 / 0.3¥18.76

单位是元/百万 token。百炼当前版比 DeepSeek 官方贵 2.9~5.7 倍——因为百炼没同步 DeepSeek 9 月 10 日那次降价,缓存价 0.2 vs 官方 0.02,差整整 10 倍。

遇到「官方不公开系数」怎么办

百炼的 Token Plan 用 Credits 抵扣,但官方文档明确写:"单次消耗的 Credits 由模型类型、Token 用量、思考模式及工具调用等动态决定",不提供系数表。我一开始想反推一个系数,后来发现那是不可靠的推测,直接删掉了。

正确做法如果有人用"套餐价 ÷ 额度"粗估,比如 ¥39/2500 ≈ ¥0.0156/Credit,再算本单约 742 Credits、占 Lite 29.7%——这些都是假设,官方从未确认 Credits 与金额的换算关系。官方途径是实际调用后从控制台用「抵扣 Credits ÷ 消耗 Token」反算系数。

第四站:智谱 GLM Coding Plan(不支持 DeepSeek)

智谱的套餐不支持 deepseek 模型,所以只能用 GLM-5.3-Flash 做同量级对照。智谱的积分区分缓存,公式是 积分 = (未命中输入×2.3 + 命中输入×0.56 + 输出×8) / 10000:

积分 = 212,119×2.3 + 55,084,928×0.56 + 177,492×8
     = 487,874 + 30,847,560 + 1,419,936
     = 32,755,370 → /10000 = 3,275.54 积分

智谱的缓存系数是 0.56 而火山是全量 0.5(不区分),所以同样 5547 万 token,智谱算出 3,275 积分,火山只有 2,773 AFP。不过这两个数不能直接比——积分和 AFP 的兑换汇率不同,要比得折算成钱。

四条线路横向对比

线路本次用量成本相对官方
DeepSeek 官方(空闲)¥2.02基准
DeepSeek 官方(高峰)¥4.05基准
火山方舟 Small 档¥40(占 13.87%)20 倍(未用满)
百炼当前版¥11.585.7 倍
百炼 0731 闲时快照¥9.384.6 倍

四条实用结论

  1. 先看缓存命中价,再看总价。缓存命中价能差 50 倍(0.02 vs 1+),这个系数比输入输出价加起来更重要。
  2. 套餐不总是更便宜。火山用满时是官方按量的 1.37~2.74 倍,因为它不区分缓存。买之前先用你的真实命中率算一遍。
  3. 关注厂商的降价节奏。百炼没跟上 DeepSeek 9/10 的降价,同一个模型就贵了 5.7 倍。锁定模型的话,官方直营通常更稳。
  4. Agent 场景要主动利用缓存。把稳定的系统提示词和项目文件放在最前面,别在中间插变化内容——前缀一变,后面全部缓存失效。这一条能把账单砍掉 99%。
数据说明计算日期 2026-09-15,用量与价格均取自官方页面截图(素材存档在 价格与倍数计算/ 目录,含各厂商价格表 OCR 原文)。官方价格会变,本文数字仅代表该时点。想估算自己项目的 token 数可以用 Token 计数器,但精确计费务必看 API 返回的 usage。

Every LLM pricing page looks similar, yet the same model can differ by more than 10x across vendors and plans. Let me run the numbers on a real Agent coding bill to show where the gap comes from.

The usage: what this bill looks like

MetricValueShare
Total tokens55,474,539100%
Input (cache hit)55,084,92899.30%
Input (cache miss)212,1190.38%
Output177,4920.32%

This distribution is typical: 99.3% cache hits. In Agent coding, system prompts and project files are re-read every turn, but with identical prefixes so they hit cache. Cache-hit pricing is 50x cheaper than cache-miss, and it alone decides the bill.

First stop: DeepSeek official pay-as-you-go (baseline)

PeriodInput missInput hitOutput
空闲¥1¥0.02¥4
高峰¥2¥0.04¥8
Actual cost of the same 55.5M-token usage across four provider routes

All figures are ¥ per million tokens. Applying this bill (off-peak):

空闲:55,084,928×0.02/1e6 + 212,119×1/1e6 + 177,492×4/1e6 = ¥2.02
高峰:55,084,928×0.04/1e6 + 212,119×2/1e6 + 177,492×8/1e6 = ¥4.05

官方价区间 = ¥2.02 ~ ¥4.05
Remember this number55.5M tokens costs ¥2–4 on official pay-as-you-go. This is the baseline for everything below.

Second: Volcengine Agent Plan (the plan costs more)

Volcengine bills in AFP: AFP = (input×0.5 + output×0.5) / 10000. The catch: AFP makes no distinction between cache hits and misses — everything counts at the same coefficient.

AFP = 55,474,539 × 0.5 / 10000 = 2,773.73 AFP

Comparing the tiers

TierMonthlyAFP quotaThis bill uses
Small¥4020,00013.87%
Medium¥200100,0002.77%
Large¥500250,0001.11%
Max¥1,000500,0000.55%

What if you use the full quota? 20,000 AFP = 400M tokens, which at this bill's 99.3% hit rate converts to official pay-as-you-go:

TierPlan priceFull quota = officialMultiple
Small¥40¥14.59 ~ ¥29.192.74 ~ 1.37×
Medium¥200¥72.9 ~ ¥145.92.74 ~ 1.37×
Large¥500¥182.4 ~ ¥364.82.74 ~ 1.37×
Max¥1,000¥364.8 ~ ¥729.62.74 ~ 1.37×
The conclusion is counter-intuitive: at full quota the plan costs 1.37–2.74x official pay-as-you-go. Official cache-hit pricing is dirt cheap at ¥0.02/M, while AFP ignores caching entirely. A plan's value isn't savings — it's model switching plus a fixed budget.

Third: Alibaba Bailian (noticeably more expensive)

VersionIn/Out/CacheCost of this bill
Current v4-flash1 / 2 / 0.2¥11.58
0731 snapshot (off-peak)1.5 / 4.5 / 0.15¥9.38
0731 snapshot (peak)3 / 9 / 0.3¥18.76

¥ per million tokens. Bailian's current version is 2.9–5.7x more expensive than DeepSeek official — they didn't follow the Sept 10 price cut, and their cache price (0.2) is 10x the official 0.02.

When vendors hide their coefficients

Bailian's Token Plan uses Credits, and the docs say: "Credits consumed depend on model type, token usage, thinking mode and tool calls" — no coefficient table provided. I tried back-solving one, realized it was speculation, and deleted it.

The right approachIf someone estimates via "plan price ÷ quota" — e.g. ¥39/2500 ≈ ¥0.0156/Credit, so ~742 Credits, 29.7% of Lite — these are assumptions; the vendor never confirmed the Credits-to-money relationship. The official path is to measure after a real call: Credits consumed ÷ tokens.

Fourth: Zhipu GLM Coding Plan (no DeepSeek support)

Zhipu's plan doesn't support DeepSeek models, so I can only compare with GLM-5.3-Flash. Its points do distinguish cache: points = (miss×2.3 + hit×0.56 + output×8) / 10000

积分 = 212,119×2.3 + 55,084,928×0.56 + 177,492×8
     = 487,874 + 30,847,560 + 1,419,936
     = 32,755,370 → /10000 = 3,275.54 积分

Zhipu's cache coefficient is 0.56 while Volcengine charges a flat 0.5, so the same 55.5M tokens yields 3,275 points vs 2,773 AFP. But these aren't directly comparable — points and AFP have different exchange rates, so convert to money first.

All four routes side by side

RouteCost of this billvs official
DeepSeek official (off-peak)¥2.02baseline
DeepSeek official (peak)¥4.05baseline
Volcengine Small¥40(占 13.87%)20x (under quota)
Bailian current¥11.585.7x
Bailian 0731 off-peak¥9.384.6x

Four practical takeaways

  1. Look at the cache-hit price first. It can differ 50x (0.02 vs 1+), which matters more than input and output prices combined.
  2. Plans aren't always cheaper. Volcengine at full quota is 1.37–2.74x official because it ignores caching. Run your own hit rate through the numbers before buying.
  3. Watch price-cut cadence. Bailian missed DeepSeek's Sept 10 cut and ended up 5.7x dearer for the same model. If you're model-locked, going direct to the vendor is safer.
  4. Exploit caching deliberately in Agent workloads. Put stable system prompts and project files first and never interleave changing content — once the prefix changes, everything after it misses. This alone can cut 99% off the bill.
Data noteCalculated 2026-09-15; usage and prices come from official page screenshots archived in the 价格与倍数计算 directory (with OCR text). Official prices change, so these numbers reflect that moment only. Use our Token Counter to estimate, but always trust the API's usage for billing.
返回文章列表